
Everything our engineers know about running SRE well — downtime root causes, MTTR, incident response, and where AI actually helps (and doesn't). Articles and comparisons, in one place.
Every SRE article we've published — downtime, MTTR, incident response, and AI in the on-call loop. Newest first.
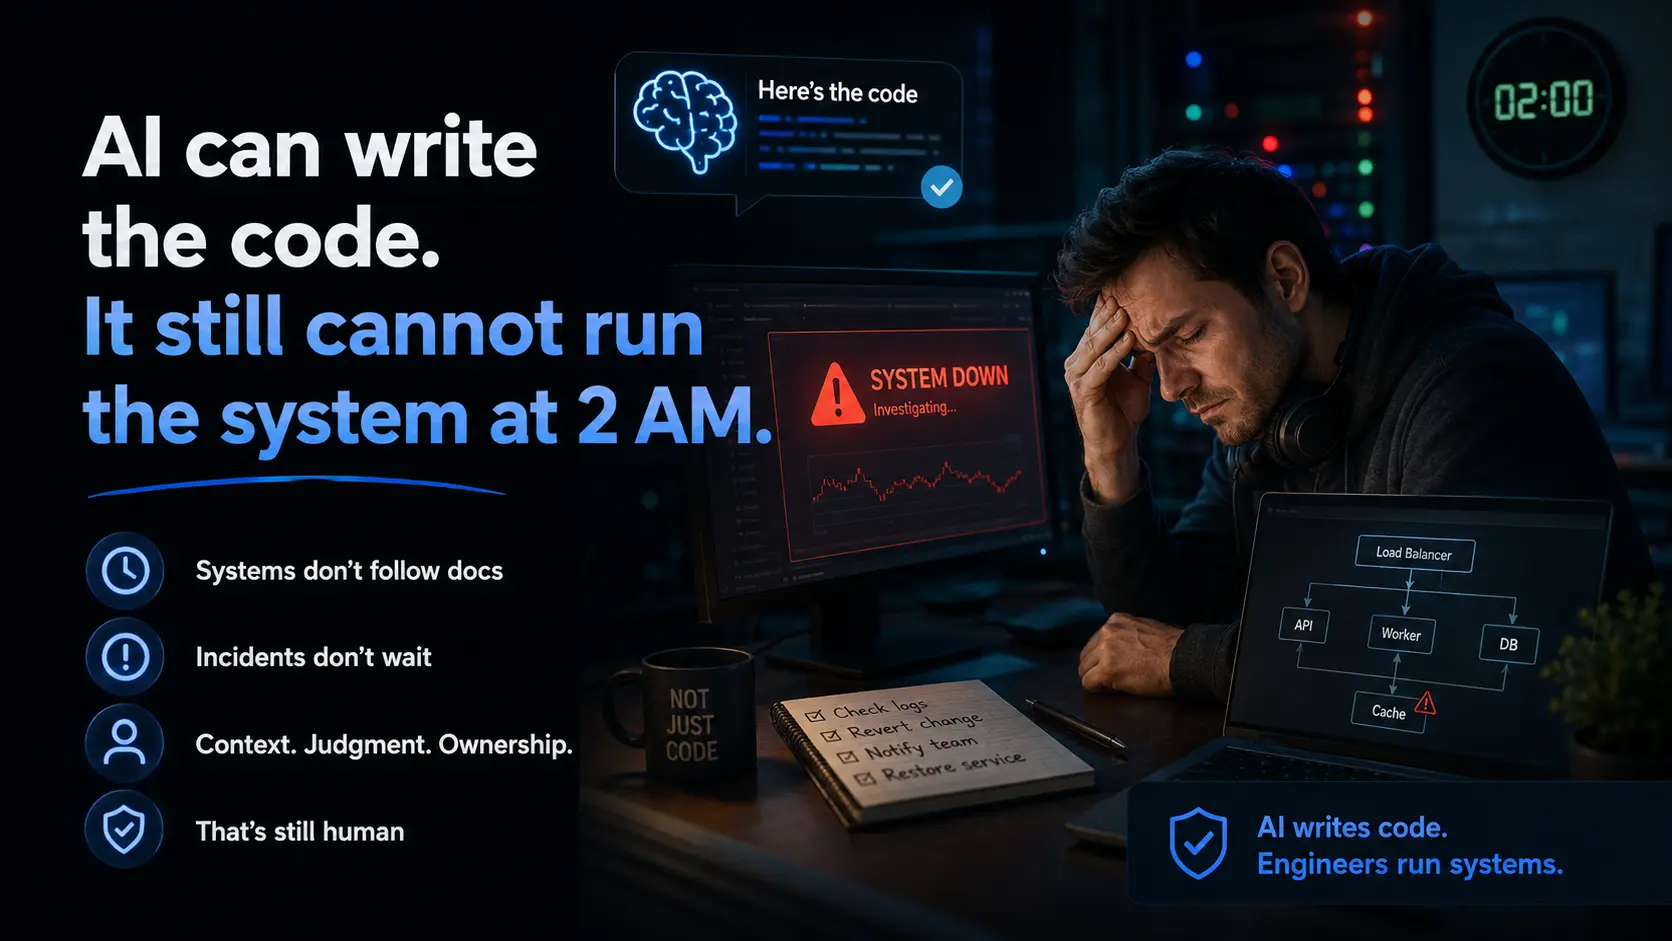
AI writes code well. It does not run distributed systems at 2 AM during a Sev-0. Here is what experienced SREs actually do during…
Read more
Learn the common causes of downtime, including infrastructure failures, outages, and misconfigurations, plus strategies to improve reliability.
Read more
Discover hidden bottlenecks affecting MTTR and learn why tooling alone cannot improve incident response, reliability, and recovery speed.
Read more
Ninety percent of IT leaders say they are confident they could recover from a ransomware attack. In practice, according to a Veeam survey of…
Read moreWhere SRE ends and DevOps or Platform Engineering begins is a common question. Start here.
Compare SRE and DevOps approaches, their key differences, benefits, and how they improve reliability, automation, and cloud operations.
Read more
Understand SRE vs Platform Engineering, key differences, responsibilities, and how teams balance reliability, developer velocity, and scale.
Read moreNew to the topic? These jump straight to the glossary entry that defines each concept in plain language.
From cutting MTTR to building an on-call practice that doesn't burn out your team, our senior engineers build and run SRE with you — not from a slide deck.