
Everything our engineers know about running observability well — metrics, logs, traces, and the practices that keep a tool rollout from becoming shelfware. Articles and comparisons, in one place.
Every observability article we've published — culture, tooling, Kubernetes observability, and why programs fail. Newest first.
Learn why many observability programs fail after deployment and how strategy, workflows, and engineering culture impact long-term success.
Read more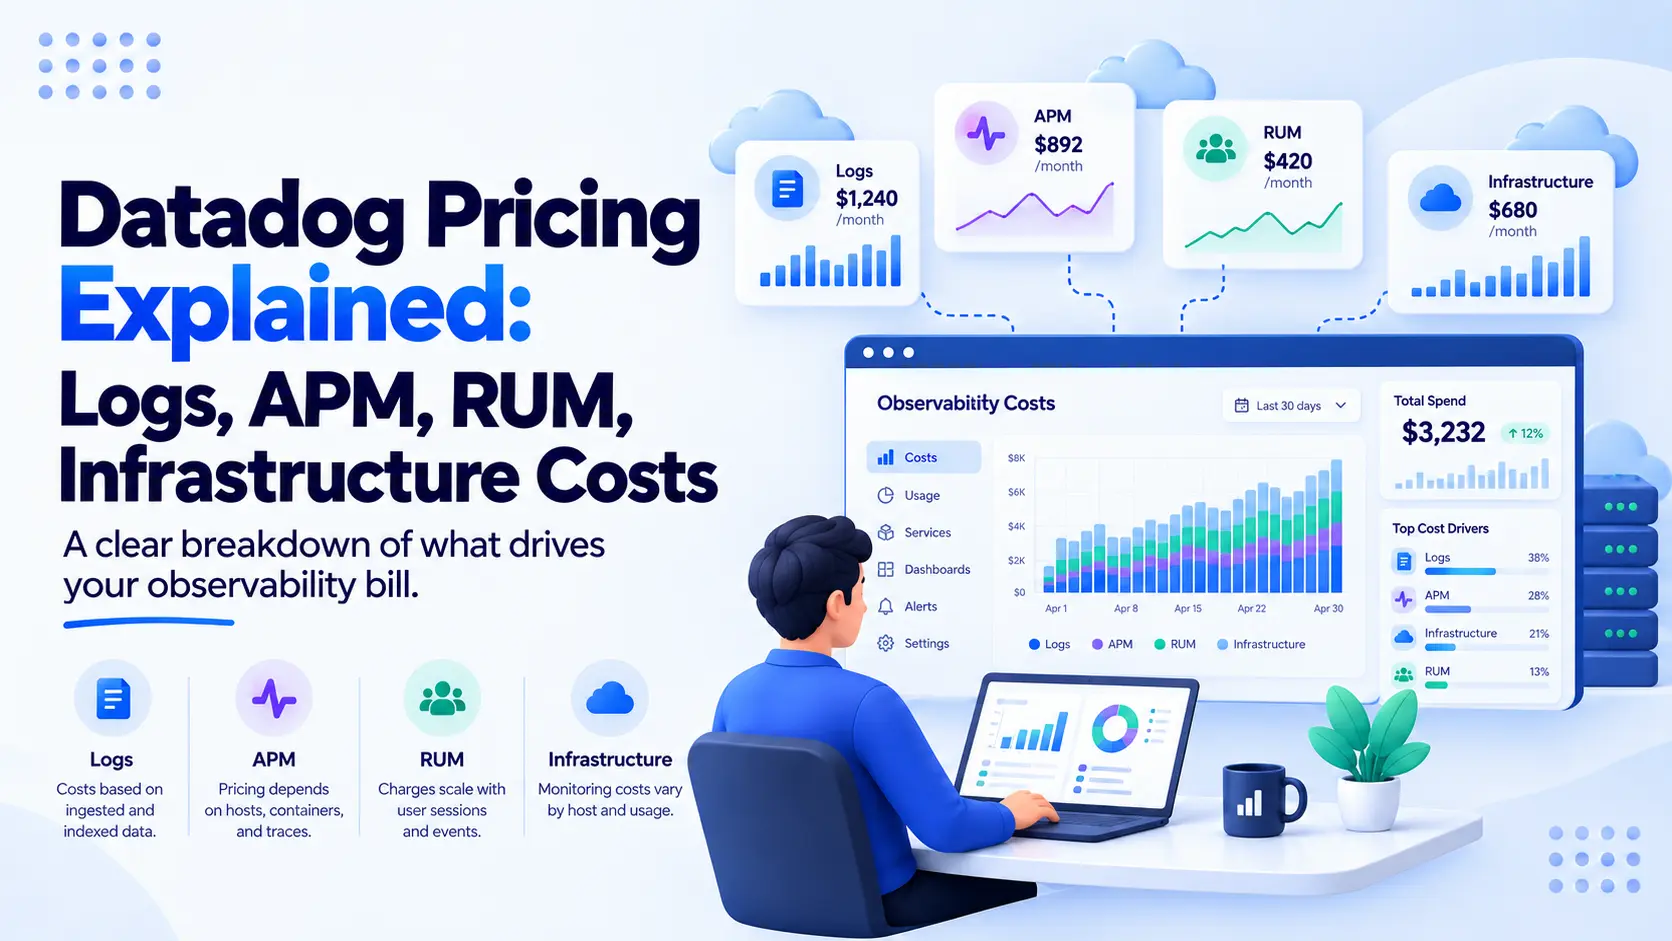
Every Datadog product and what it actually costs, per host, per GB, per session, per committer. The real numbers, not the sales deck.
Read more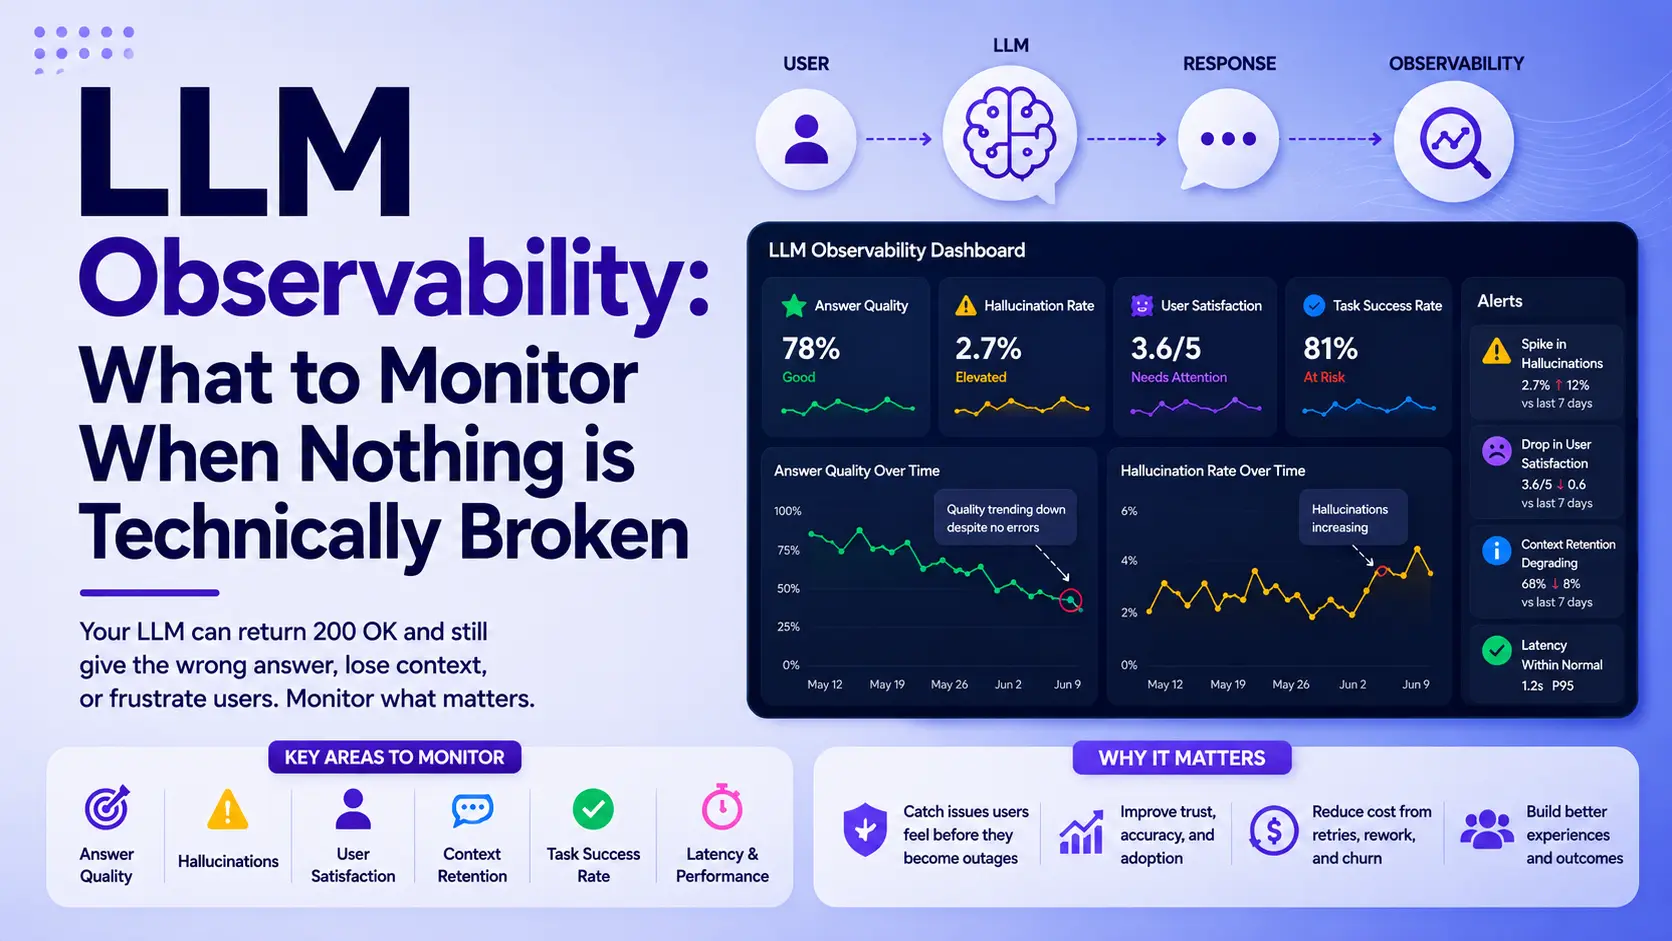
LLM observability explained: what to monitor, which open-source tools to use, and why OpenTelemetry's GenAI conventions still aren't stable. With 2026 survey data.
Read more
73% of organizations run hybrid cloud, but most still can't see across it. A practical guide to unified visibility: telemetry architecture, egress costs, and…
Read more
Most Kubernetes teams get thousands of alerts a week and only 3% need action. Here is how to fix your alerting in 5 days…
Read more
Discover hidden bottlenecks affecting MTTR and learn why tooling alone cannot improve incident response, reliability, and recovery speed.
Read more
Learn how unified observability improves Kubernetes monitoring, logging, tracing, performance visibility, and incident response across platforms.
Read more
Learn how business process monitoring improves operational visibility, performance tracking, automation, and issue detection across workflows.
Read more
A practical guide to Kubernetes observability covering metrics, logs, and traces, plus expert insights, common challenges, best practices, and tools to help teams improve…
Read more
The success of DevOps has never been about tools alone—it thrives on collaboration, agility, and shared responsibility. Yet, as software systems grow more complex,…
Read more
In today’s fast-paced digital world, organizations are racing to deliver applications and services with speed, scalability, and reliability. DevOps has emerged as a vital…
Read moreNot sure where monitoring ends and observability begins? Start here.
Meta description: A practical guide to Datadog alternatives for Kubernetes teams. The real options, what each pricing model does to a K8s bill, and…
Read more
Production-grade observability for a US banking SaaS on AWS EKS—fully automated, private, and multi-tenant. Unified metrics, logs, and traces with Grafana LGTM, zero public…
Read more
Learn the difference between monitoring and observability, including metrics, logging, tracing, incident detection, and system visibility.
Read moreNew to the topic? These jump straight to the glossary entry that defines each concept in plain language.
From a first OpenTelemetry rollout to fixing a program that stalled after the tools went in, our senior engineers build and run observability with you — not from a slide deck.